easysnowdata.stations.archive.load#
- easysnowdata.stations.archive.load(stations: Any = None, *, aoi: Any = None, variables: Any = None, time: Any = None, networks: Any = None, source: str | None = None, hemisphere: str = 'auto') Dataset[source]#
Daily SWE and snow depth for many stations, from the published archive.
- Parameters:
stations – Station codes, or an inventory frame.
Nonewith no aoi means every station in the archive — which is the point of this route.aoi – Any form
easysnowdata.aoi.parse_aoi()accepts; picks the stations when stations isNone.variables –
"swe","snwd"or both (the default). The archive holds nothing else;easysnowdata.stations.load()does.time – Any form
easysnowdata.temporal.parse_time()accepts. Each station’s series is cut to the window before the dense grid is built, so a narrow window is cheap — on the bundle route it is still downloaded whole, because that is how it is published.networks – Keep only these networks.
source –
"github-pages-zarr"(default) reads the chunked store on that repo’s Pages site and fetches only the chunks the request touches: named stations up to 64 come fromby_station.zarr(a whole record is one chunk), anything wider fromby_time.zarr(one water year of every station is one or two chunks). Itstimeaxis is complete and daily between the first and last observation, and its values are stored as float32 (returned as float64), so they agree with the CSV routes to float32 precision. When the store cannot be read and no source was asked for, the snapshot route below is used instead, with a warning naming the snapshot."github-tarball"downloads the ~28 MB bundle of CSVs attached to that repo’s latest snapshot release — a few times a year, each with a Zenodo DOI — and reads every wanted CSV out of it. Ask for it when a result should be pinned to a citable snapshot; the Dataset’ssnapshot_tagandsnapshot_published_atsay which one. Itstimeaxis holds only days on which some station observed."github-csv"fetches one CSV per station instead, which needs neither a store nor a temporary file.hemisphere – Which water year to attach.
"auto"(default) gives each station its own hemisphere’s: 1 October in the north, 1 April in the south (named for the year it starts, so water year N peaks in calendar year N in both). When the stations span both hemispheres,water_yearanddowyare(station, time)coordinates;groupby("water_year")works on them,swap_dimsneeds one station selected first."northern"or"southern"applies one convention to every station.
- Returns:
xarray.Dataset–sweandsnwdin centimetres with dims(station, time), station metadata (withhemisphere) onstationand water-year coordinates ontime, or on(station, time)for a load that spans both hemispheres.
Notes
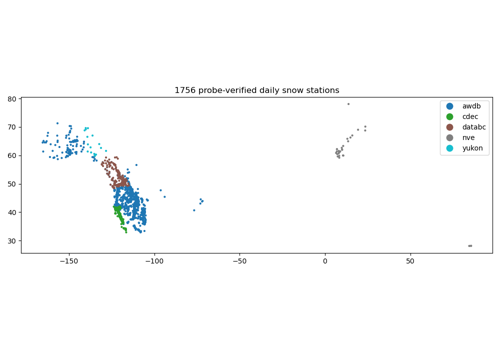
The whole archive is about 1 550 stations by 47 000 days, so asking for all of it materializes roughly 1.2 GB of float64 (measured on the tarball route: 31 s and under 2 GB of peak memory). Pass time, aoi or stations when you do not need every cell — on the default route that also cuts the download to the chunks touched, measured at 0.7 MB for one water year of every station and 0.5 MB for one station’s whole record.
Examples
>>> import easysnowdata as esd
>>> archive_ds = esd.stations.archive.load()  # every daily station
Examples using easysnowdata.stations.archive.load#
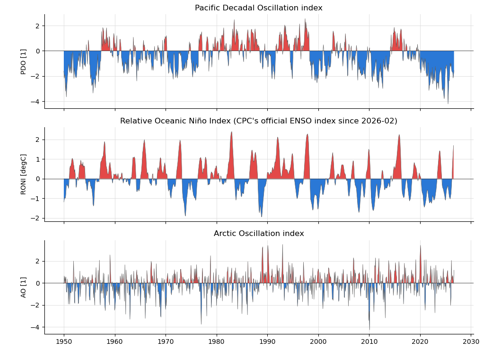
Climate-mode indices: PDO, ENSO, AO (NOAA NCEI / CPC / PSL)